I’ve spent the last three-plus years running technical SEO audits, for lead-gen sites, ecommerce catalogues, and everything in between and if there’s one thing that never changes, it’s this: most “SEO audits” people download from a tool aren’t audits at all. They’re warning lists. A real technical SEO audit is an investigation into whether search engines can actually find, understand, and trust your most valuable pages.
So let me answer the question the way I’d answer it on a client call:
A technical SEO audit is a structured examination of a website’s crawlability, indexability, rendering, performance, architecture, security, and search-engine accessibility. Its purpose is to identify technical issues that stop important pages from being discovered, understood, indexed, or used effectively.
That’s the textbook version. In practice, the real value of an audit isn’t a list of 200 issues, it’s figuring out which handful are actually costing the business traffic, rankings, or revenue, and which ones are noise a crawler flagged because that’s what crawlers do.
Google itself treats crawling and indexing as two distinct stages of search visibility, not one combined process, which is exactly why I never lump “crawlability” and “indexability” into the same checklist item during an audit. They fail independently, and they need to be diagnosed independently.
If you’re not sure where your own site stands on any of this, it’s usually the first thing we look at when we run a technical SEO audit at Raxivo Digital, before touching a single keyword or backlink.
Technical SEO vs. Broader SEO, Where an Audit Actually Sits
One thing I always clarify with clients before I even open a crawler: technical SEO is not the whole SEO puzzle, and treating it that way is how audits end up overpromising.
In my experience, SEO breaks down into five connected but distinct disciplines:
- Technical SEO: can search engines access, render, and index your pages?
- On-page SEO: are individual pages optimised for the right keywords and intent?
- Content SEO: does the content itself satisfy the searcher and demonstrate expertise?
- Off-page SEO: does the site have the external signals (links, mentions, authority) to compete?
- Local SEO: is the business set up correctly for location-based search?
A technical audit only really covers the first bucket. That distinction matters because I’ve seen plenty of businesses commission a “technical SEO audit” expecting it to explain why their content isn’t ranking, when the honest answer was their content itself needed work, not their site’s plumbing. A full SEO audit looks at all five areas together; a technical audit deliberately narrows the lens to infrastructure.
What a Technical Audit Can Reveal
When I run one properly, here’s what typically surfaces:
- Pages search engines cannot crawl
- Pages that are crawlable but blocked from indexing
- Duplicate or conflicting URL signals
- JavaScript rendering problems hiding content from bots
- Slow or unstable page experiences
- Broken internal links and orphan pages
- Migration and redirect failures
- Structured-data errors
- Wasted crawl budget
- Technical barriers quietly hurting conversions, not just rankings
What It Cannot Guarantee
This is the part a lot of agencies gloss over, and it’s where I think honesty actually builds more trust than a polished pitch deck. A technical audit cannot guarantee:
- Rankings
- Traffic growth
- Automatic Core Web Vitals improvements just because issues are “fixed”
- Rich-result eligibility from schema alone
- AI-search visibility from technical fixes alone
Fixing your robots.txt file doesn’t rank you for competitive terms. What it does is remove the ceiling that was capping your content and authority from ever getting a fair shot in the first place.
Tool Output vs. Professional Audit
A technical SEO tool identifies patterns, duplicate titles, broken links, missing tags. A professional audit connects those patterns to things a tool has no visibility into: organic traffic and which keywords are actually valuable, revenue pages versus pages nobody cares about, page templates, conversion data, crawl behaviour from server logs, and realistic implementation effort against business priorities. A tool tells you what’s wrong. An audit tells you what’s worth fixing first, and why.
Why Does Technical SEO Matter for Organic Performance?
I like explaining this with an analogy I’ve used with non-technical clients for years: technical SEO doesn’t grow your rankings, it builds the road your content and authority travel on. You can have the best-written page on the internet, but if the road’s blocked, nobody, not users, not Googlebot, is getting there.
Crawlability supports discovery.
Before anything else can happen, search engines need to find your pages. A few things drive this:
- Robots.txt controls what crawlers are allowed to access
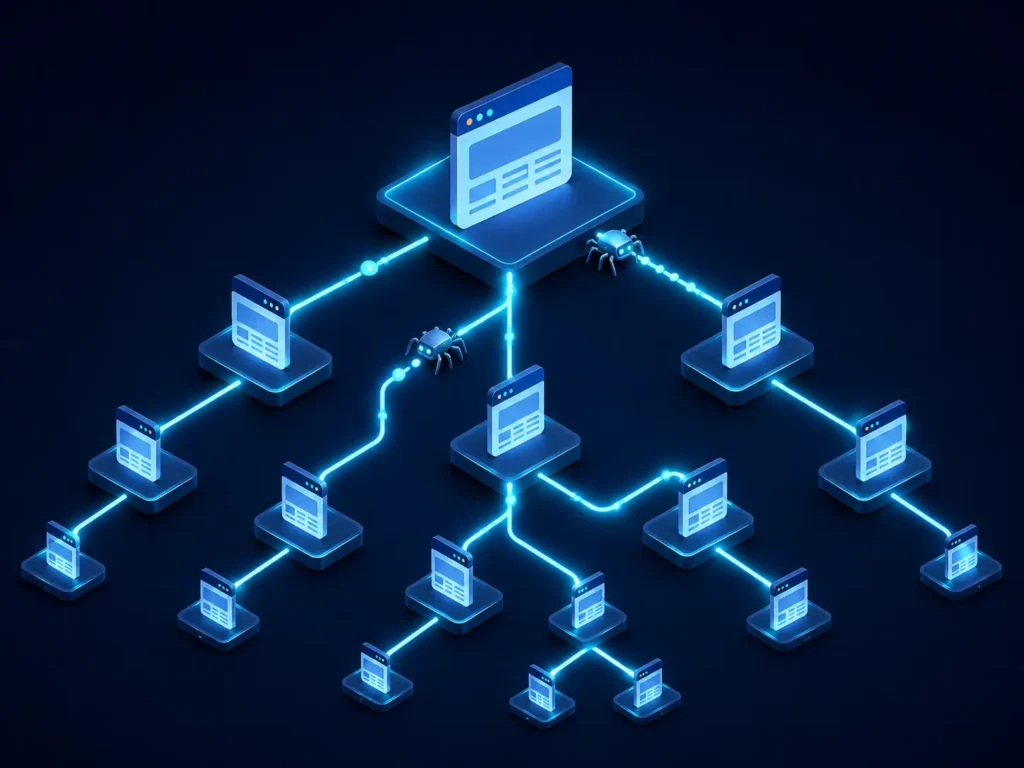
- Internal links help search engines discover new and existing URLs
- XML sitemaps communicate which URLs you consider important
- Crawlable HTML links give bots an actual discoverable path, not a JavaScript-only button that only humans can click
And this isn’t just my opinion, server logs reveal what bots actually request, which is often very different from what a site owner assumes is being crawled. I’ve caught more than one client whose most “important” page, by their own account, hadn’t been crawled in months.
Indexability supports eligibility.
Being crawlable doesn’t mean being indexable, a distinction I have to explain constantly. Google explicitly treats crawling and indexing as separate parts of search visibility, and I check them separately for exactly that reason. The main levers here are noindex directives, canonical URLs, HTTP status codes, duplicate content, soft 404 pages, sitemap and canonical consistency, and what Google Search Console’s indexing states actually show.
Performance supports user experience.
This is where Core Web Vitals come in, a practical framework, not a vanity scorecard:
| Metric | What It Measures | Good Threshold |
|---|---|---|
| LCP | Loading performance | 2.5 seconds or less |
| INP | Interaction responsiveness | 200 milliseconds or less |
| CLS | Visual stability | 0.1 or less |
Based on the 2025 HTTP Archive Web Almanac, only 48% of mobile sites and 56% of desktop sites passed all three Core Web Vitals, meaning a significant chunk of the web is still failing at least one metric. In my own audits, that ratio tracks closely with what I see in the wild, especially on sites carrying too many third-party scripts.
And performance isn’t just a technical vanity metric, it correlates with real business outcomes. Vodafone reported an 8% increase in sales after achieving a 31% improvement in LCP through A/B testing. Tokopedia saw a 55% LCP improvement paired with a 23% increase in average session duration.
I want to be careful here, the same way I am with clients: these are correlation examples, not proof that fixing your LCP will produce identical results. Every site’s baseline, traffic mix, and competitive landscape is different. But they’re strong enough signals that I never treat performance work as “nice to have.”
Technical quality supports business outcomes.
Ultimately, technical SEO creates the conditions under which content, links, and authority can actually produce results. A technically flawless page still needs to be genuinely useful and backed by real authority. But even excellent content can quietly underperform for years if search engines can’t reliably access, render, or index it.
Performance isn’t just a technical vanity metric, it correlates with real business outcomes. Documented case studies show Vodafone reported an 8% increase in sales after achieving a 31% improvement in LCP through A/B testing, and Tokopedia saw a 55% LCP improvement paired with a 23% increase in average session duration. I’m careful here, the same way I am with clients: these are correlation examples, not proof that fixing your LCP will produce identical results, but they’re strong enough signals that I never treat performance work as “nice to have.”
How Do We Check Crawlability and Site Architecture?
This is where I actually open a crawler, and it’s the part of an audit I find most satisfying, crawlability issues are usually fixable in a day, yet they can silently cap a site’s performance for years.
Robots.txt Accessibility
The first thing I check, every single time, before anything else: robots.txt. I’ve lost count of how many “why did our traffic drop overnight” panic calls turned out to be a single accidental disallow rule pushed live with a site update. I specifically look for:
- Accidental disallow rules
- Blocked CSS and JavaScript
- Disallowed folders
- Environment and staging directives left in by mistake
- Rules affecting important page types
That last one especially – I’ve seen entire product categories get blocked because someone copied a staging robots.txt file into production without checking it.
Internal-Link Structure
Once I know Google can reach the site, I check whether it’s being guided efficiently. Internal links are still one of the most underrated levers in technical SEO, in my experience. I look at:
- Sitemap declaration
- Crawlable HTML links (not JS-only click handlers)
- Whether important pages are actually receiving internal links
- Descriptive anchor text
- Contextual links within body content
- Navigation consistency across templates
- Links pointing to redirects instead of final URLs
- Links pointing to broken URLs
Click Depth and Orphan Pages
I flag any important page sitting more than three or four clicks from key hub pages, and I assess weak category-to-detail relationships, flat versus hierarchical structures, breadcrumb implementation, and topic hubs with their supporting pages.
Orphan pages get separate attention because they never show up in a basic tool scan but can be genuinely costly: URLs present in the sitemap but absent from internal links, pages receiving organic traffic but no internal support, pages discovered only through external links, and important pages disconnected entirely from the site architecture. I’ve found revenue pages living as complete orphans, technically indexed, technically ranking a little, but with zero internal link equity feeding them. Fixing that alone has produced some of the fastest wins I’ve delivered.
Crawl Traps and Server Logs
Especially on ecommerce sites, I spend real time on faceted navigation, because it can quietly create thousands of low-value URLs that eat crawl budget, filter combinations, URL parameters, internal search results, calendar archives, infinite pagination or sort loops, session IDs, and duplicate category paths.
Then I compare what I think is happening against what Googlebot is actually doing through server logs: request frequency, important pages receiving little crawl activity, excessive crawling of low-value parameters, repeated 4xx responses, 5xx errors during crawl spikes, and crawl activity by URL pattern.
One caveat I always give clients: crawl-budget analysis matters most for large or frequently updated websites, Google’s own technical guidance discusses crawl-budget management specifically in that context. For a 40-page brochure site, I won’t spend hours here. For a 50,000-SKU catalogue, it’s often where the biggest wins hide.
How Do We Check Indexability and URL Signals?
Once I know a page is crawlable, my next question is always the same: is this actually the URL Google is choosing to index and is it the right one? “Crawlable” and “indexed” are two separate gates, and confusing them is where a lot of audits go wrong.
Indexation Directives and Canonical Tags
I start by checking every layer that could be telling search engines to stay out, meta robots tags, X-Robots-Tag headers, noindex directives, nofollow usage, conflicting page-level and header-level directives, and staging-site controls left active after launch.
Canonicals cause more confusion than almost anything else I audit. I look for missing canonicals, self-referencing canonicals, canonicals pointing to redirects instead of final destinations, canonicals pointing to non-indexable or entirely unrelated pages, and conflicts between canonicals, internal links, and XML sitemaps. If your canonical tag says one thing, your internal links say another, and your sitemap says a third, you’re not giving Google a clear signal, you’re giving it a vote to break the tie however it wants.
HTTP Status Codes and Duplicate Content
I map the full status code landscape across the site, 200 pages, 3xx redirects, 4xx client errors, 5xx server errors, soft 404s, and custom error pages that incorrectly return a 200 status. That last one is a classic: a “page not found” screen that technically returns 200 OK. Google sees a real, indexable page. Users see an error.
Duplicate content shows up differently depending on the site, but the usual suspects are parameter variations, HTTP and HTTPS versions both live, WWW and non-WWW versions both live, trailing-slash variations, duplicate category paths, printer-friendly pages, thin location pages, and similar product or service pages competing against each other.
Google Search Console and Sitemap Quality
GSC is where I go for the ground truth on indexation, reviewing each coverage state individually: indexed pages, crawled but not indexed, discovered but not indexed, duplicate without user-selected canonical, alternate page with proper canonical, excluded by noindex, blocked by robots.txt, server errors, and soft 404s.
Last, I check sitemap quality: only canonical, indexable URLs should be included, no redirects, no 4xx or 5xx URLs, accurate lastmod values, separate image/video/news sitemaps where relevant, and sitemap coverage compared against internal links and GSC data. A sitemap full of redirected or noindexed URLs doesn’t just look sloppy, it actively wastes crawl attention on pages you don’t even want indexed.
How Do We Audit JavaScript and Rendered Content?
This is the section I’ve seen create the most disagreement between developers and SEOs, and I understand both sides. Developers want to build fast, modern JavaScript-driven experiences. My job is making sure that ambition isn’t quietly costing the business its search visibility. I treat rendering as its own diagnostic stage, separate from crawlability and indexability, because a page can pass both of those and still fail here.
Raw HTML Versus Rendered HTML
I always compare the raw HTML response against the fully rendered version, because they can tell two very different stories: content visible in the raw response versus content added after JavaScript execution, internal links available before rendering, and metadata and structured data generated by JavaScript. If your titles, descriptions, or schema are injected client-side, there’s a real chance Google is seeing a blank shell on first pass and hoping its rendering queue catches up later. For product, service, or article pages specifically, I want to confirm the core content, the stuff that actually answers the searcher’s query, is genuinely visible after rendering.
JavaScript SEO Risks
From there, I go looking for the specific failure patterns I’ve learned to expect on JavaScript-heavy sites:
- Client-side-only primary content
- JavaScript-generated links that never resolve into crawlable HTML anchors
- Failed hydration
- Blocked JavaScript files preventing rendering entirely
- Lazy-loaded content with no crawlable alternative
- Rendering delays and incomplete server-side rendering
- JavaScript-generated canonicals
That last one is a genuine chicken-and-egg problem, Google has to render the page correctly just to find out which URL it’s even supposed to treat as canonical.
Rendering Validation
To validate all of this, I lean on a combination rather than any single tool: Google Search Console’s URL Inspection, direct rendered-HTML comparison, mobile and desktop rendered crawls, browser console errors, JavaScript-disabled testing, and Lighthouse or PageSpeed diagnostics.
One thing I’m careful to explain to every client running a JavaScript framework: Google treats crawling and rendering as genuinely separate stages, and publishes dedicated JavaScript SEO guidance specifically because of this. That’s an important nuance, a JavaScript-heavy site isn’t automatically bad for SEO. I’ve audited plenty that perform perfectly well. The risk isn’t the framework itself; it’s whether the implementation gives search engines a reliable, complete version of the page without requiring perfect rendering conditions every time.
How Do Technical SEO Tools Support the Audit?
No single technical SEO tool gives you a complete diagnosis. I use a combination, and each one answers a different piece of the puzzle. Relying on just one, even a good one, is how audits end up with blind spots.
Crawler Tools and Google's Own Tools
For the core site crawl, I typically reach for Screaming Frog, Sitebulb, Semrush Site Audit, Ahrefs Site Audit, JetOctopus, or Lumar, depending on the site size and what I need to extract.
But Google’s own tools are non-negotiable for me, because they’re the closest thing to seeing what Google itself sees: Google Search Console, URL Inspection, PageSpeed Insights, Lighthouse, Rich Results Test, and the Search Console Core Web Vitals report.
Technical Diagnostics
Beyond the core crawlers and Google’s tools, I bring in specialised diagnostics depending on what the audit surfaces, Google Analytics, Chrome DevTools, WebPageTest, GTmetrix, SSL Labs, Schema Markup Validator, log-file analysis platforms, and browser rendering tests.
Tool Limitations
This is the part that matters most, and it’s why I never let a tool’s output stand in for judgment. Crawlers may not represent Googlebot exactly. Lab scores may not represent real users. GSC data can be delayed. Third-party crawlers may interpret JavaScript differently than Googlebot does. A tool warning is not automatically an SEO priority. Tools identify symptoms; experts diagnose causes.
That last point is really the whole philosophy behind how I run audits. A crawler will happily hand you 400 “issues.” My job is figuring out which three of those are actually costing the business money.
Tool-to-Question Table
I find it’s more useful to think about tools by the question they answer, rather than by category:
| Question | Recommended Source |
|---|---|
| Can Google access the page? | Robots.txt Tester, URL Inspection and rendered crawl |
| Is the page indexed? | Search Console and indexed-URL testing |
| Which URLs does Googlebot request? | Server logs |
| Is the page fast for real users? | CrUX and Search Console |
| What causes the slow experience? | PageSpeed Insights, Lighthouse and DevTools |
| Are links and redirects correct? | Screaming Frog, Sitebulb or another crawler |
| Is structured data eligible? | Rich Results Test and Schema Markup Validator |
| Are important pages well connected? | Crawler link reports and internal-link analysis |
How Do We Identify and Prioritise Technical SEO Issues?
This is the section I care about more than any other, because it’s genuinely where audits succeed or fail. I’ve seen beautifully thorough audits get shelved entirely because they handed the client 300 flagged issues with no sense of what to actually do first. My whole approach is built around avoiding that outcome.
Issue Classification
Every finding gets sorted into one of four tiers before anything else happens:
- Critical: prevents crawling, indexing, or access to important pages
- High: affects valuable templates, revenue pages, or large URL groups
- Medium: creates duplication, inefficiency, or weaker signals
- Low: a best-practice improvement with limited immediate impact
Prioritisation Factors
Within each tier, I weigh a set of factors before deciding what actually goes to the top of a client’s roadmap: business impact, SEO impact, number of affected URLs, page value, evidence strength, implementation effort, time sensitivity, and migration or launch risk.
The Priority Formula
The formula I keep coming back to, based on years of running these audits, boils down to a few core principles: don’t prioritise by issue count, prioritise valuable pages and templates over sheer volume of warnings, confirm whether a warning actually affects search visibility before acting on it, avoid treating every broken link as if it’s a ranking penalty, separate genuine Google requirements from general best practice, and include a fix and a validation method for every important finding, not just a description of the problem.
Audit Issue-Register Format
This is the actual format I use to present findings to clients, because a flat list of bugs doesn’t help anyone make a decision. Here’s how I structure it, with real example rows from audits I’ve run:
| Finding | Evidence | Affected Scope | Impact | Recommendation | Owner | Priority | Validation |
|---|---|---|---|---|---|---|---|
| Canonicals point to redirected URLs | Crawler export | Product template | Indexation ambiguity | Point canonicals to final 200-status URLs | Developer | High | Recrawl and inspect in GSC |
| 90,000 post-migration 404s | Server and crawler data | Legacy URL set | Lost access and user friction | Map relevant old URLs to equivalent destinations | SEO and Developer | Critical | Redirect crawl and traffic monitoring |
| Slow mobile LCP | CrUX and PSI | Service template | Poor mobile experience | Optimise hero image and critical rendering path | Developer | High | Recheck field and lab data |
Every row follows the same discipline, finding, evidence, scope, impact, recommendation, owner, priority, and how we’ll validate it worked. If I can’t fill in that last column, I usually take it as a sign the finding needs more investigation before it belongs on the roadmap at all.
These principles align closely with expert guidance on delivering high-impact technical SEO audits, the idea being that an audit is only as good as its ability to drive real, prioritised action, not the size of the issue list it generates.
What Technical SEO Case Studies Show About Implementation?
I always include real case studies in an audit conversation, because abstract principles are easy to nod along to and easy to forget. Numbers from actual implementations tend to stick. That said, I’m careful about how I frame them, the goal is to show what technical SEO can produce through specific, deliberate interventions, not to wave around a vague “we improved site health” claim.
Saramin - Indexation and Structured Data Improvements
I mentioned this one earlier in the structured-data section, but it’s worth revisiting here for the fuller picture. Google’s own Saramin case study documents a programme built around indexation fixes, canonicalisation, duplicate-content cleanup, and structured data (JobPosting, Breadcrumb, and estimated-salary markup). The results reported were significant: organic search traffic roughly doubled, new organic sign-ups increased by 93%, and conversion rate improved by 9%.
Seer Interactive, Post-Migration Recovery
This is one of the more dramatic technical SEO recovery stories I reference, because it illustrates exactly how much damage a poorly executed migration can do and how much can be recovered with a properly prioritised fix. Following a redesign and CMS migration, the site’s traffic initially fell by 26%. The subsequent audit uncovered 163,198 URLs without proper redirects and roughly 90,000 404 pages, alongside excessive indexed parameters, duplicate content, and canonical issues. After remediation, the case study reports a 125% traffic increase, alongside 30% organic revenue growth and 25% transaction growth.
I bring this one up with any client going through or planning, a migration, because it’s a genuinely useful illustration of both the risk and the recoverability involved.
How I Interpret Case-Study Results
I never present these numbers as a promise, and I think that honesty is actually part of what makes an audit credible rather than salesy. A few things I keep in mind, and communicate directly to clients:
- Results are context-specific to that business, market, and starting point
- Multiple changes were often implemented together, not in isolation
- Correlation does not prove that one single technical fix caused every outcome
- The best evidence includes a clear baseline, a defined intervention, a timeframe, and a measurement method
I use case studies to illustrate what’s possible, not to promise identical results, because every site I’ve audited has a different baseline, and pretending otherwise is how agencies end up overpromising and under-delivering.
What Should You Remember About a Technical SEO Audit?
If there’s one thing I want a reader to walk away with, it’s this: a professional technical SEO audit is really trying to answer five questions, in this order,
- Can search engines discover the important pages?
- Can they crawl and render the content correctly?
- Are the correct URLs eligible for indexing?
- Can users access and interact with the pages efficiently?
- Which fixes should the business implement first?
Everything I’ve walked through, crawlability, indexability, rendering, tools, prioritisation, ultimately exists in service of those five questions. Based on my own experience running these audits across very different niches and site sizes, the sites that see results aren’t the ones with the fewest flagged issues. They’re the ones where the right issues got fixed first, and where someone actually went back to confirm the fix worked.
So here’s the core message I’d leave you with: technical SEO is not about collecting the largest number of warnings. It’s about finding the technical issues that restrict valuable pages, explaining their real impact, recommending realistic solutions, and proving whether the fixes actually worked.
If any of this resonated with where your own site might be sitting right now, request a technical SEO audit, download the technical SEO checklist, or book a consultation with a technical SEO specialist.
Frequently Asked Questions
What is technical SEO?
Technical SEO is the discipline of ensuring search engines can crawl, render, and index a website correctly, while giving users a fast, accessible experience.
What does a technical SEO audit include?
It covers crawlability, indexability, rendering, Core Web Vitals, structured data, mobile and international signals, security, and prioritised recommendations for fixing what’s found.
How do you conduct a technical SEO site audit?
By preparing with business context and access, segmenting the site by template, and systematically checking crawlability, indexability, rendering, performance, and search understanding before prioritising and validating fixes.
What's the difference between a technical SEO tool and a professional audit?
A tool identifies patterns and warnings; a professional audit connects those patterns to business impact, page value, and realistic priorities.
Can a technical SEO audit increase organic traffic?
It can remove the barriers preventing your content and authority from performing but it doesn’t guarantee rankings or traffic on its own.
Written from three-plus years of hands-on technical SEO audit work across UK service businesses and ecommerce sites. If you’d like a second pair of eyes on your own site’s technical health, the team at Raxivo Digital runs these audits every week.